|
Cheng Chen I am a final-year Ph.D. candidate at the College of Computing and Data Science, Nanyang Technological University, advised by Prof. Guosheng Lin and Dr. Fayao Liu. I am currently a research intern at XPENG Robotics, working on world models and robot learning. Previously, I interned at Ant Group on video generation and interactive generative video. I received my M.Eng. and B.Eng. degrees from Fudan University. My research spans embodied AI, controllable video generation, and world models. I am passionate about how foundation models learn to act and adapt through interaction. Feel free to reach me at cheng021 AT e.ntu.edu.sg. Email / CV / Google Scholar |
|
|
I am actively seeking opportunities in both industry and academia, and expect to complete my Ph.D. in late 2026. |
News
|
ResearchI study how foundation models turn general knowledge into reliable action. My current work in embodied AI investigates how demonstrations and action–outcome feedback help agents understand unfamiliar robots, and whether task skills and embodiment knowledge can be acquired separately and recombined. In parallel, I develop controllable video generation and world models for sustained interaction with digital characters, joint video–action prediction, and transferring human experience into robot training data. My earlier work includes text-to-3D generation and recovering editable CAD models from images. Selected publications. * indicates equal contribution. |
|
XPACE: Joint World and Action Modeling from Heterogeneous Experience
Jiacheng Wei, Jerry Bai, Xiaoyu Yue, Zidong Wang, Xiaoyang Guo, Cheng Chen, Fanqi Pu, Fan Wu, et al. Technical report, 2026 project page / arXiv Joint world and action modeling from human and robot experience, with simulation-generated recovery data for policy improvement. |
|
|
AnyWorld: Factorized Egocentric World Models for Cross-Embodiment Generalization
Cheng Chen, Jerry Bai, Jiacheng Wei, Boyu Chen, Xiaoji Zheng, Fan Wu, Minghao Yang, Tianrun Chen, Ruibo Li, Xiaoyu Yue, Xiao-Yang Guo, Yixiao Ge, Guosheng Lin, Fayao Liu Conference on Robot Learning (CoRL), 2026 project page / arXiv Recomposing unpaired human interaction into robot-native experience across embodiments, viewpoints, and scenes. |
|
|
DiVA: Enabling Interactive Digital Life Simulation via Video Models
Cheng Chen, Hao Ouyang, Qiuyu Wang, Ka Leong Cheng, Wen Wang, Yihao Meng, Hanlin Wang, Yixuan Li, et al. International Journal of Computer Vision (IJCV), under review, 2026 project page / arXiv A stateful video-generation system for long-running interactive character worlds with stable multi-turn behavior. |
|
|
SwiftVLA: Unlocking Spatiotemporal Dynamics for Lightweight VLA Models at Minimal Overhead
Chaojun Ni*, Cheng Chen*, Xiaofeng Wang, Zheng Zhu, Wenzhao Zheng, Boyuan Wang, Tianrun Chen, et al. IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026 project page / arXiv A lightweight vision-language-action model with explicit spatiotemporal dynamics for efficient robot deployment. |
|
|
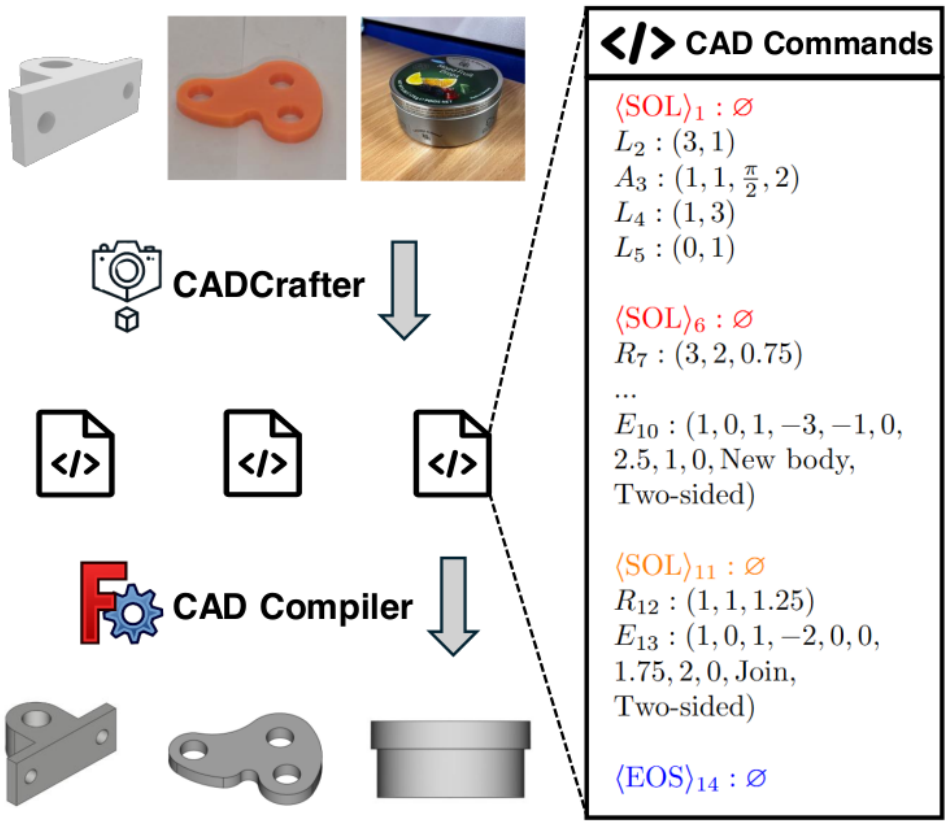
CADCrafter: Generating Computer-Aided Design Models from Unconstrained Images
Cheng Chen, Jiacheng Wei, Tianrun Chen, Chi Zhang, Xiaofeng Yang, Shangzhan Zhang, Bingchen Yang, Chuan-Sheng Foo, Guosheng Lin, Qixing Huang, Fayao Liu IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025 arXiv Recovering editable parametric CAD programs from unconstrained images. |
|
|
Text-to-Image Rectified Flow as Plug-and-Play Priors
Xiaofeng Yang, Cheng Chen, Xulei Yang, Fayao Liu, Guosheng Lin International Conference on Learning Representations (ICLR), 2025 paper / code Using text-to-image rectified-flow models as flexible optimization priors for downstream visual generation. |
|
|
Sculpt3D: Multi-View Consistent Text-to-3D Generation with Sparse 3D Prior
Cheng Chen, Xiaofeng Yang, Fan Yang, Chengzeng Feng, Zhoujie Fu, Chuan-Sheng Foo, Guosheng Lin, Fayao Liu IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2024 project page / arXiv Injecting sparse 3D priors into text-to-3D generation to improve geometry and multi-view consistency. |
|
|
Learn to Optimize Denoising Scores: A Unified and Improved Diffusion Prior for 3D Generation
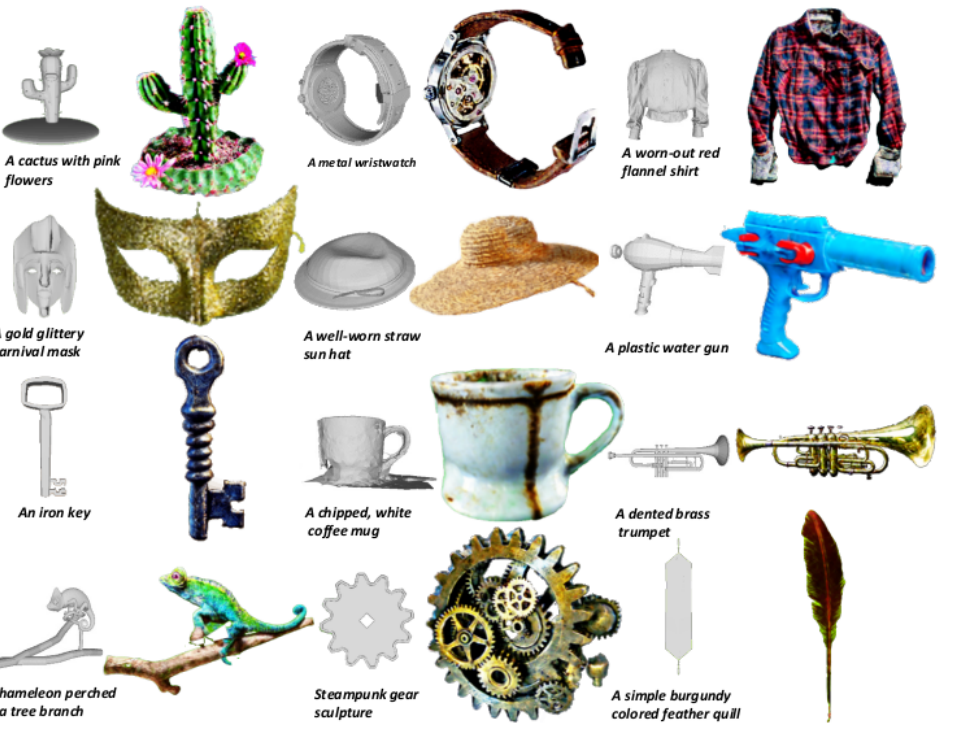
Xiaofeng Yang, Yiwen Chen, Cheng Chen, Chi Zhang, Yi Xu, Xulei Yang, Fayao Liu, Guosheng Lin European Conference on Computer Vision (ECCV), 2024 project page / arXiv / code A learnable diffusion prior that improves score-distillation-based 3D generation in a unified formulation. |
|
For the complete list, please see my Google Scholar. |
Honors
|
Talks
|
Services
|
VisitorsLoading globe… |